Human Oversight Should Follow Risk, Not Habit

Tony Ruiz
“A human reviews every output” sounds safe. At volume, it often produces slow queues, shallow review, and unclear accountability.
The opposite—letting AI act without intervention—can be equally careless.
The practical answer is risk-based oversight. Microsoft's 2026 Work Trend Index found that 86% of surveyed AI users treated AI output as a starting point and stayed responsible for the thinking; quality control and critical thinking ranked as the two most important human skills as AI takes on more work. Anthropic's 2026 agentic coding report similarly describes a shift toward automated routine verification with human attention focused on novel, boundary, and strategic cases.
Human attention is limited. Design where it creates real protection.
Score the decision, not the technology
Oversight should depend on the action's characteristics:
- Consequence: What harm can an incorrect action cause?
- Reversibility: Can the result be corrected quickly and completely?
- Uncertainty: How clear are the data, policy, and requested outcome?
- Novelty: Is this a familiar pattern or an unseen situation?
- Authority: Does the system advise, prepare, execute, or reverse?
- Evidence: Can correctness be verified deterministically?
The same agent may operate under several oversight levels within one workflow.
Use four practical tiers
| Tier | Example | Oversight pattern |
|---|---|---|
| Low | Drafting an internal summary | Automated checks and sampling |
| Moderate | Preparing a customer response | Review uncertain or policy-sensitive cases |
| High | Changing a reservation or issuing credit | Approval before execution above defined limits |
| Critical | Employment, credit, clinical, or safety decision | Qualified human authority with documented evidence |
The tier should determine approval, logging, sampling, escalation, and monitoring requirements.
Reassess the tier when authority, data, users, or business consequences change.
Review exceptions, not clean cases
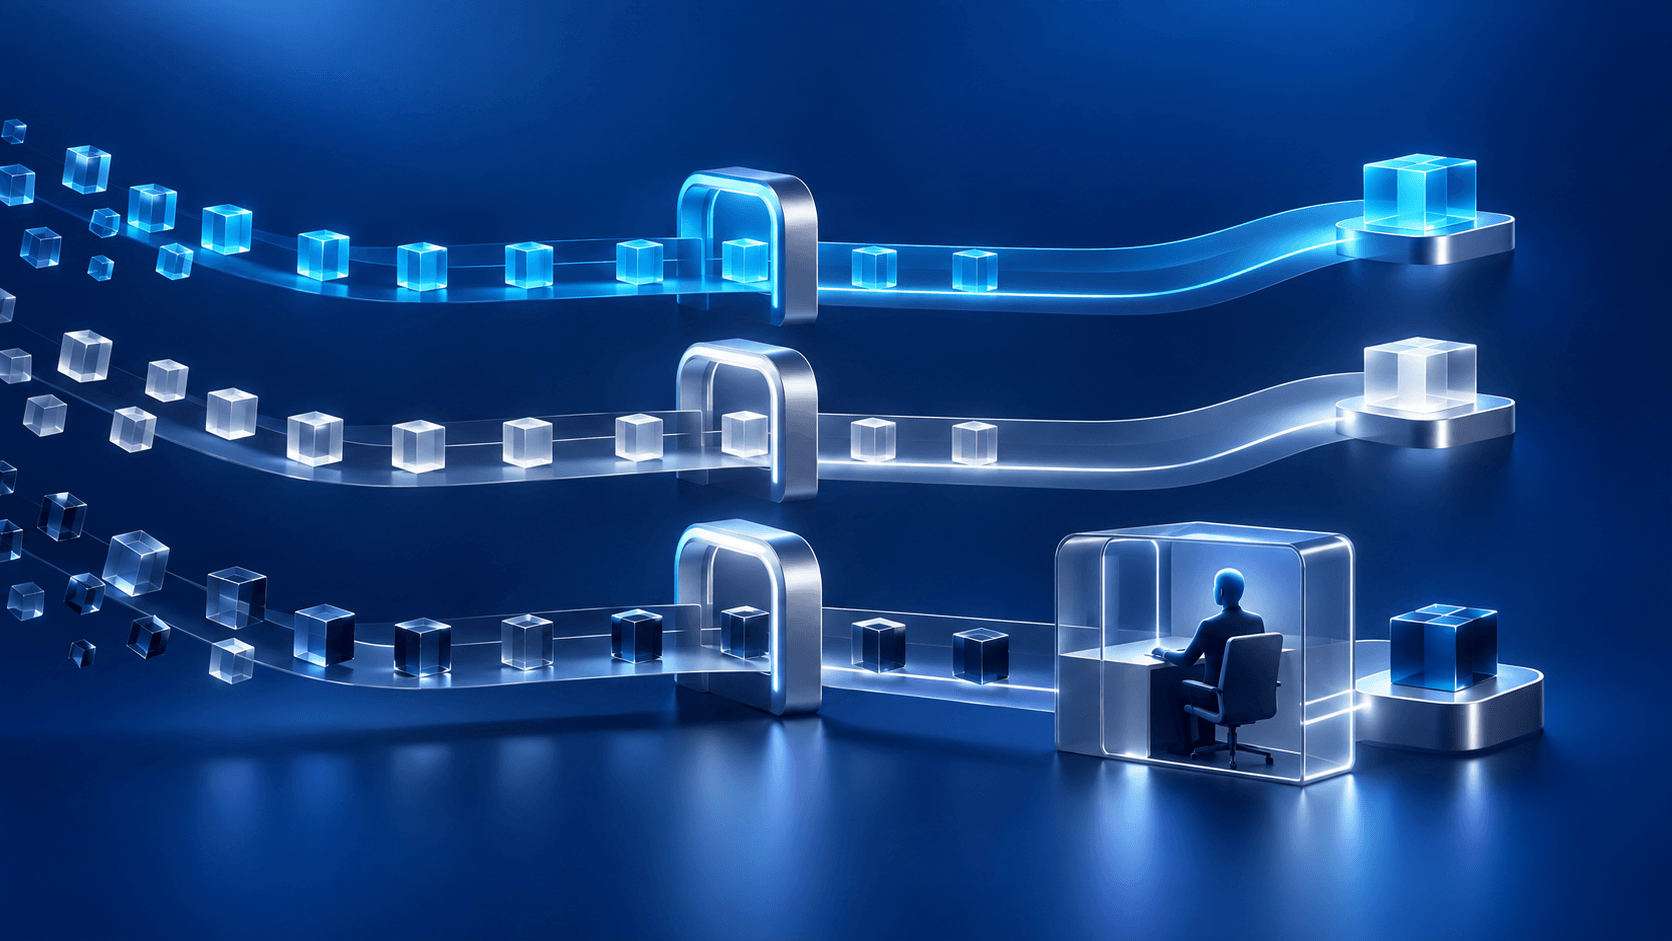
For suitable lower-risk work, let deterministic controls and confidence signals identify cases that need attention:
- missing or conflicting data;
- policy edge cases;
- unusual amounts or destinations;
- low evaluation confidence;
- new tool or model behavior;
- customer challenge; or
- failed final-state verification.
This lets skilled people spend more time reasoning and less time clicking “approve” on predictable work.
Give reviewers usable evidence
Human-in-the-loop fails when reviewers see only the model's conclusion. Show the original request, relevant sources, policy, proposed action, uncertainty, prior steps, and expected consequence.
Make approval meaningful: the reviewer needs enough time, expertise, independence, and authority to disagree.
Test the oversight system
Measure override quality, false approvals, false escalations, queue time, reviewer agreement, and incidents by tier. Seed known difficult cases to verify that escalation works. Rotate or pause reviewers when fatigue rises.
Human review is not a ceremonial control. It is one component in a system that also needs policy enforcement, evaluations, observability, and recovery.
Cayru helps organizations design risk-based human–AI workflows that protect consequential decisions without forcing people to recheck every low-risk output.
Tier one AI workflow by consequence, reversibility, uncertainty, authority, and evidence.
Related: Redesign the workflow first and embed governance in release gates.